|
1
|
|
|
2
|
- De novo genome assembly
- Gene finding from assembled contigs
- Gene annotation
|
|
3
|
|
|
4
|
- To find out coding region on genome sequence
|
|
5
|
- For each gene….
- Conserved?
- Domain?
- Function?
|
|
6
|
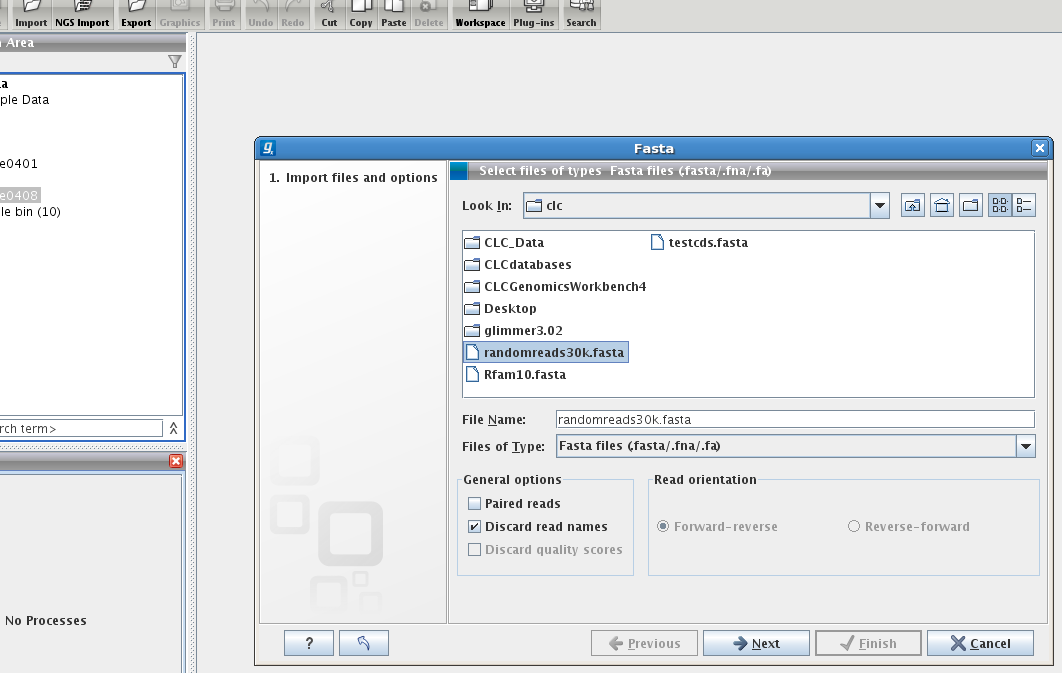
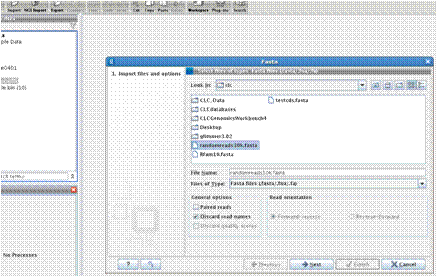
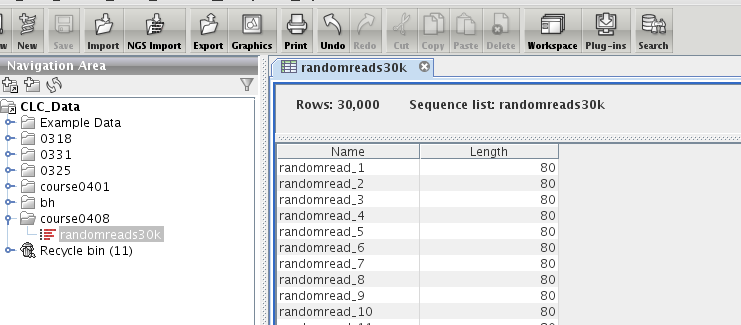
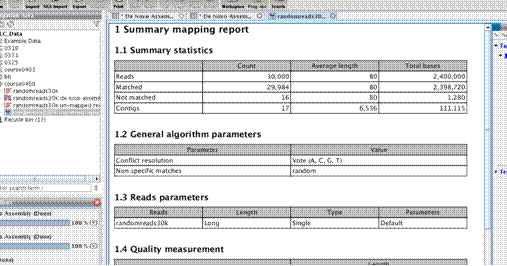
- download a random generated reads file
- http://163.25.92.61/course/randomreads30k.fasta
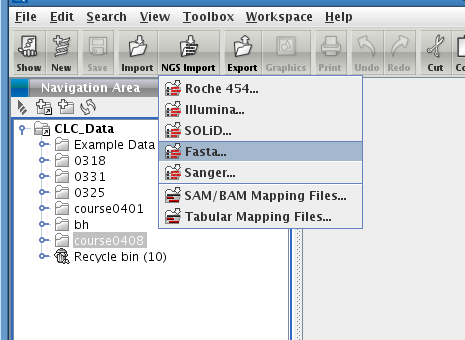
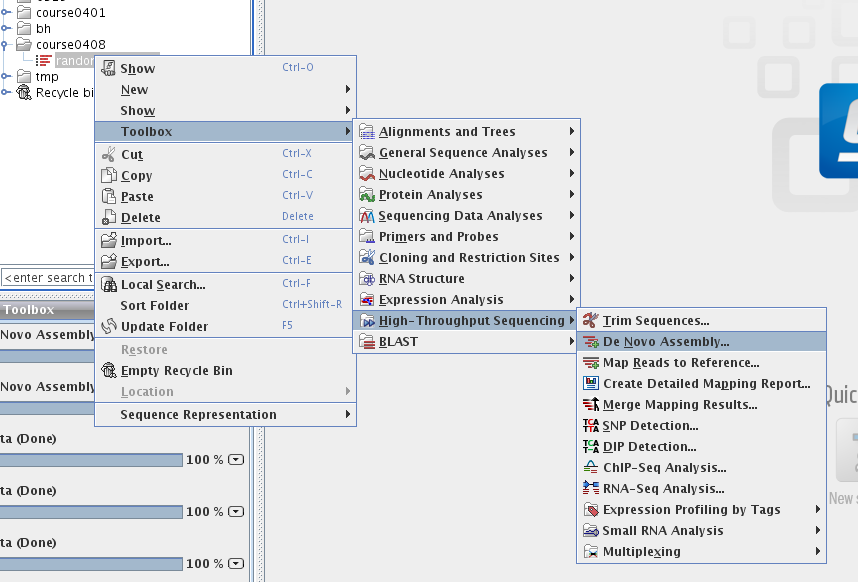
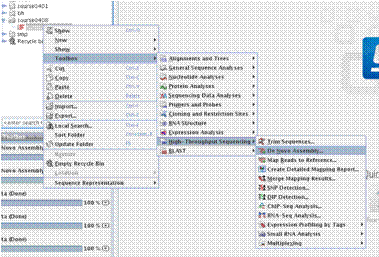
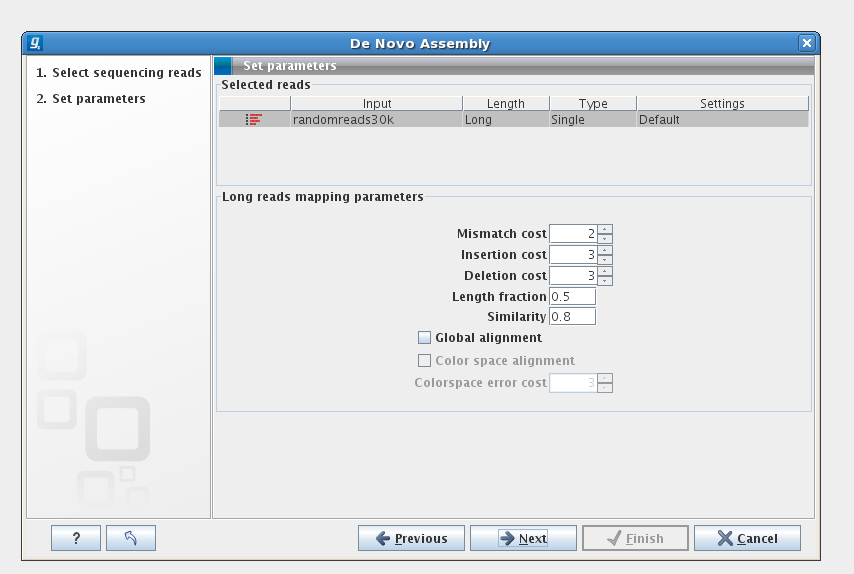
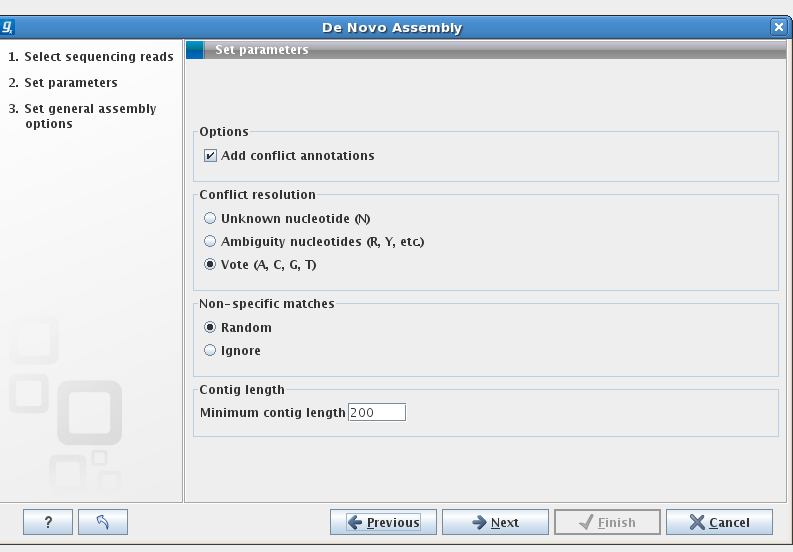
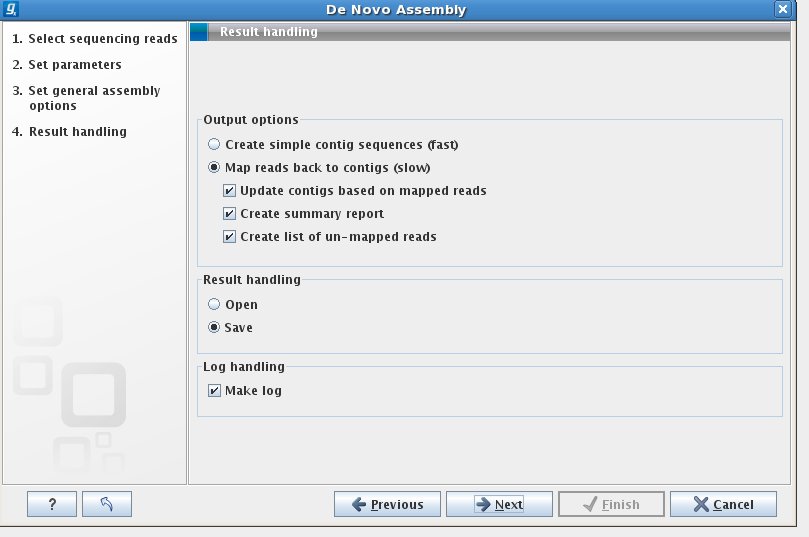
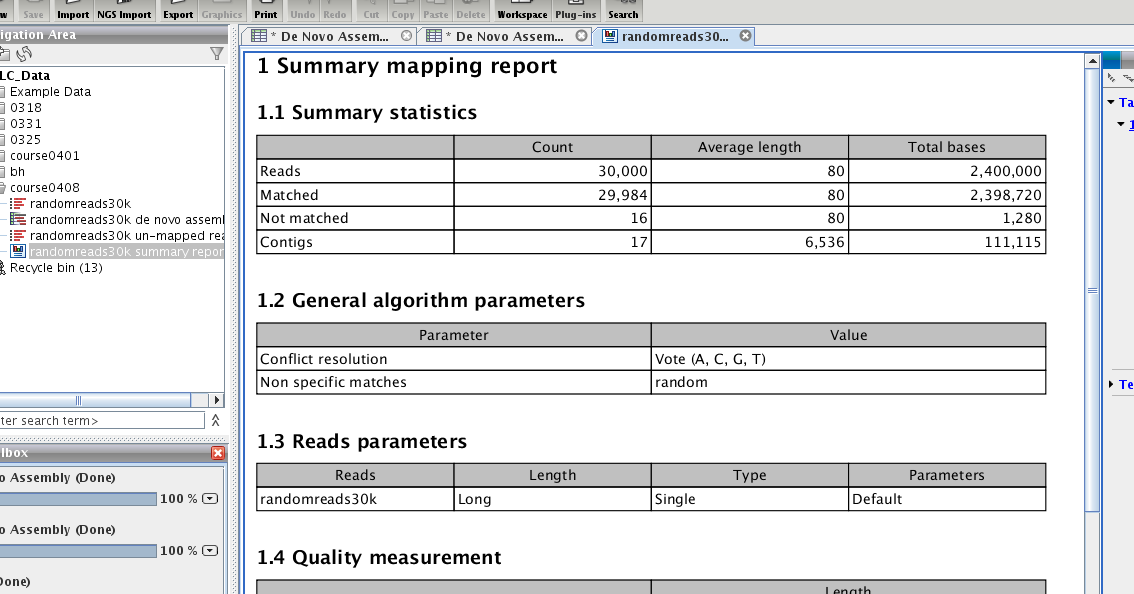
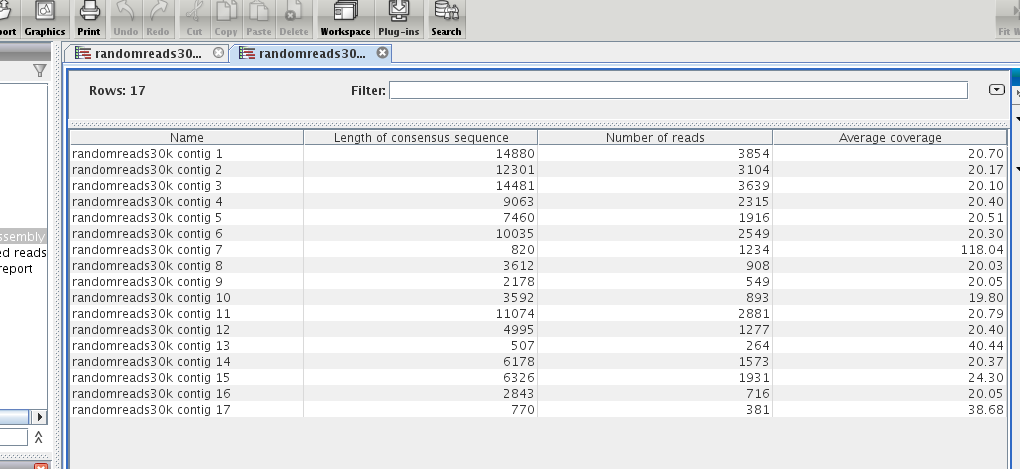
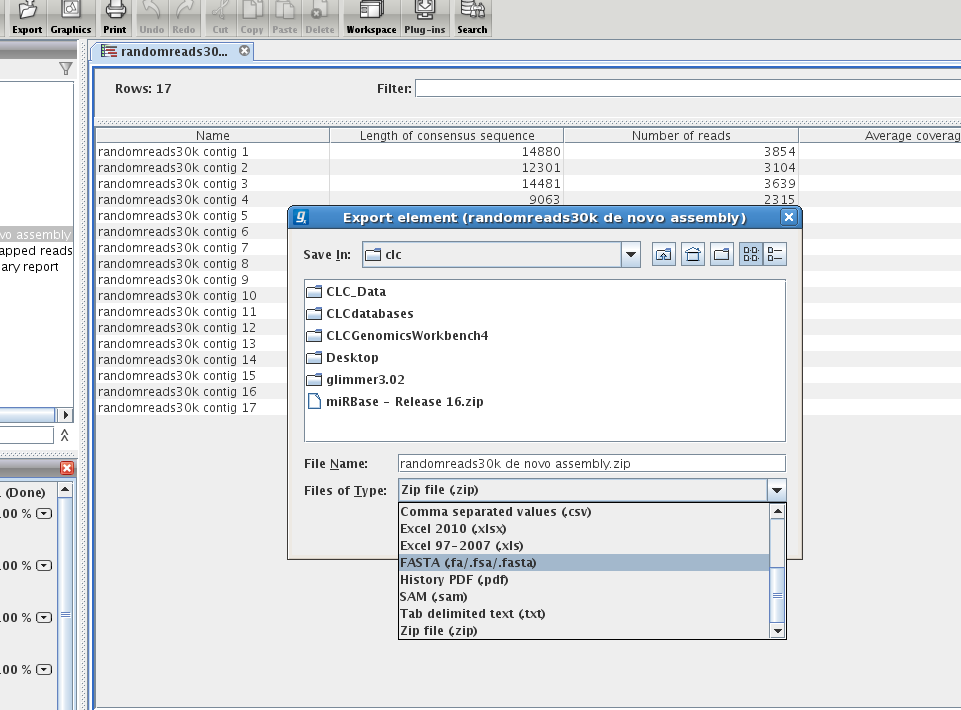
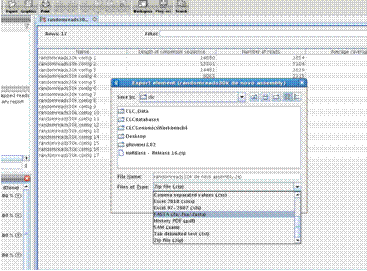
- open CLC to assemble contigs from reads
|
|
7
|
|
|
8
|
|
|
9
|
|
|
10
|
|
|
11
|
|
|
12
|
|
|
13
|
|
|
14
|
|
|
15
|
|
|
16
|
|
|
17
|
- Glimmer is a system for finding genes in microbial DNA, especially the
genomes of bacteria, archaea, and viruses.
- (Gene Locator and Interpolated Markov ModelER)
- http://www.cbcb.umd.edu/software/glimmer/
- Center for Bioinformatics & Computational Biology, University of
Maryland
- Paper about Glimmer 1.0
- S. Salzberg, A. Delcher, S. Kasif, and O. White. Microbial gene
identification using interpolated Markov models, Nucleic Acids Research
26:2 (1998), 544-548.
- Glimmer2.0
- A.L. Delcher, D. Harmon, S. Kasif, O. White, and S.L. Salzberg.
Improved microbial gene identification with GLIMMER, Nucleic Acids
Research 27:23 (1999), 4636-4641.
- Glimmer 3.0
- A.L. Delcher, K.A. Bratke, E.C. Powers, and S.L. Salzberg. Identifying
bacterial genes and endosymbiont DNA with Glimmer. Bioinformatics 23:6
(2007), 673-679.
|
|
18
|
|
|
19
|
- wget
http://163.25.92.61/course/glimmer302.tar.gz
|
|
20
|
- extract
- tar zxvf glimmer302.tar.gz
- tree -d glimmer3.02/
- go into directory of glimmer’s source code
- compile the binary code
- executable binary will be located in
|
|
21
|
- Trainning model from…
- Known genes
- Genes from evolutionary relative organism
- Open reading frames
|
|
22
|
- long-orfs
- This program identifies long, non-overlapping open reading frames
(orfs) in a DNA sequence file.
- extract
- This program reads a genome sequence and a list of coordinates for it
and outputs a multifasta file of the regions specified by the
coordinates
- build-icm
- This program constructs an interpolated context model (ICM) from an
input set of sequences.
- glimmer3
|
|
23
|
- glimmer3.02/scripts/
- g3-from-scratch.csh genome.fasta mygenome
- The script would then run the commands:
- long-orfs -n -t 1.15 genome.fasta mygenome.longorfs
- extract -t genome.fasta mygenome.longorfs > mygenome.train
- build-icm -r mygenome.icm < mygenome.train
- glimmer3 -o50 -g110 -t30 genom.seq mygenome.icm mygenome
|
|
24
|
>gi|15638995|ref|NC_000919.1| Treponema pallidum subsp.
pallidum str. Nichols, complete genome
orf00001 4 1398 +1
6.22
orf00003 1641 2756 +3
2.89
orf00004 2776 3834 +1
5.47
orf00005 3863 4264 +2
2.77
orf00006 4391 6832 +2
7.08
orf00007 6832 7074 +1
0.25
orf00008 7317 7967 +3
6.92
orf00009 7997 8260 +2
2.91
orf00010 9515 8340 -3
2.80
orf00011 9838 9984 +1
0.10
orf00013 10237 10362 +1
6.02
orf00014 10396 12378 +1
3.77
orf00015 12545 13210 +2
8.04
|
|
25
|
- vi
../scripts/g3-from-scartch.csh
- set awkpath = /fs/szgenefinding/Glimmer3/scripts
- set glimmerpath = /fs/szgenefinding/Glimmer3/bin
- set awkpath = ~/glimmer3.02/scripts
- set glimmerpath = ~/glimmer3.02/bin
|
|
26
|
- w 儲存
- q 離開vi
- wq 儲存後離開
- q! 不儲存就離開
|
|
27
|
- extract
- Usage:
- extract
genome_file
coord_file
>
fasta_file
|
|
28
|
- use home-made script to re-format
- coordinate file
- http://163.25.92.61/course/multipredict.pl
- multi-extract
- Usage:
- multi-extract
genome_file
coord_file
>
fasta_file
|
|
29
|
|
|
30
|
- The BLAST client, or blastcl3, bypasses the web browser and interacts
directly with the NCBI BLAST server that powers the NCBI web BLAST
service
- ftp://ftp.ncbi.nlm.nih.gov/blast/executables/release/LATEST/
- But you can download here…
- cd ~ (go back to your home
directory)
- wget
http://163.25.92.61/course/netblast-2.2.25-ia32-linux.tar.gz
- extract
- tar zxvf
netblast-2.2.20-ia32-linux.tar.gz
|
|
31
|
- netblast-2.2.25/bin/
- ./blastcl3 -p program -i input_sequence -d dbname -o output_file
- -p (blastn, blastx, blastp, tbastn tblastx)
- -i (query file, predice
genes here)
- -d (database name)
- nr, NCBI non-redundant database
- -o (output file)
|
|
32
|
|
|
33
|
- ./blastcl3
- -p blastn
- -i
mygene.fasta
- -d nt
- -o mygeneblast.html
- -m 2
- -K 1
- -T T
|

 備忘錄